01 / Question & finding
Clean accuracy does not tell us how the model behaves under a perturbation designed to fool it.
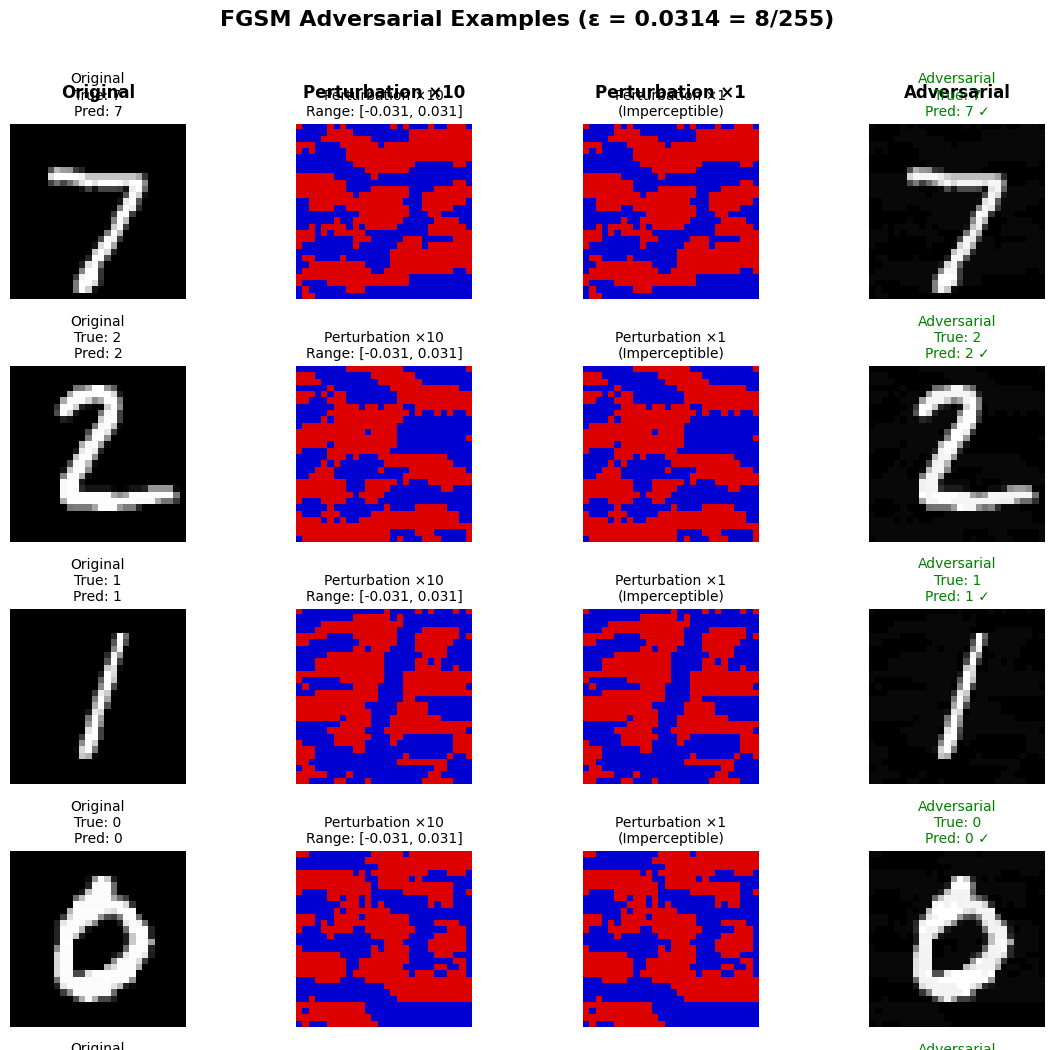
The project starts from a 99% accurate MNIST CNN and asks a simple question. Can an almost invisible pixel perturbation change its decision? And can adversarial training reduce that risk without hurting normal accuracy? An adversarial example is deliberately modified to trigger a model error while remaining visually close to the original input.
Clean-image accuracy: the starting model is already highly accurate.
Robust accuracy drops under attack, showing why clean accuracy alone is incomplete.
Adversarial training recovers 0.90 percentage point while clean accuracy remains 99.13%.
Main finding: the defense helps in this protocol, but the absolute gain is modest. Attack success falls from 2.07% to 1.29% at ε=8/255, a 0.78-point drop even though the relative reduction is about 38%.
02 / Setup
A controlled experiment with fixed parameters and saved artifacts.
MNIST
60,000 training images and 10,000 test images.
CNN · 3,274,634 parameters
Two convolution layers, two fully connected layers and dropout.
03 / Experiment
The same protocol compares the model before and after defense.
FGSM (Fast Gradient Sign Method) uses the model gradient to modify each pixel within a limit ε. Here ε is 2/255, 4/255 or 8/255: the larger ε becomes, the more freedom the attacker has to perturb the image.
Measure the baseline
Train the CNN for five epochs on clean images and measure normal test accuracy.
Attack it
Generate FGSM examples at the three ε levels and measure how much accuracy drops.
Harden and retest
Retrain for eight epochs with 50% clean and 50% adversarial examples at ε=8/255, then replay the exact same tests.
04 / Results & interpretation
The hardened model is more robust at every tested attack level without sacrificing clean accuracy.
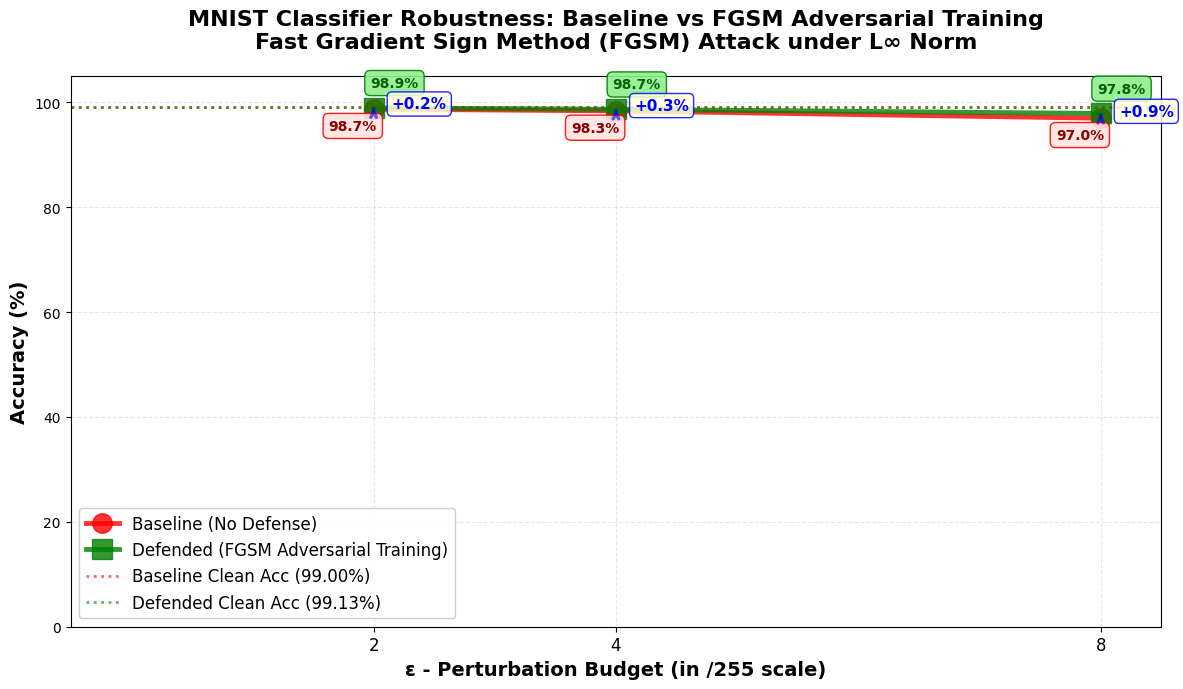
The useful conclusion is not that the model becomes invulnerable. Controlled exposure to adversarial examples improves FGSM robustness, especially at the strongest tested perturbation, without a visible clean-accuracy trade-off. From a security perspective, the experiment also shows why clean accuracy is not enough: a model should be tested against inputs deliberately designed to fool it.
05 / Reproducibility
Parameters, models, results and plots were saved.
The parameters, models, results and plots used for the evaluation were preserved in the project artefacts. Controls include L∞ bounds, input-gradient availability and visual inspection of perturbations. A public repository will be added after the original source has been recovered, cleaned and verified.
06 / Limits
FGSM is a useful first baseline, not a complete robustness evaluation.
Stronger iterative attacks such as PGD and broader suites such as AutoAttack are needed before making general robustness claims.
Results do not automatically transfer to complex images or production models.
07 / Conclusion
The experiment shows a real improvement, but only within the tested protocol.
The baseline CNN was already robust on MNIST. Adversarial training improves it further, but the absolute gain remains below one accuracy point under FGSM at ε=8/255.
A robustness claim should always name the attack, its intensity and the clean-performance trade-off. Here the conclusion is useful because it stays bounded: FGSM on MNIST validates an experimental approach, not general robustness against all adversarial attacks.